Interact with me: Joint Egocentric Forecasting of Intent to Interact, Attitude and Social Actions
TL;DR
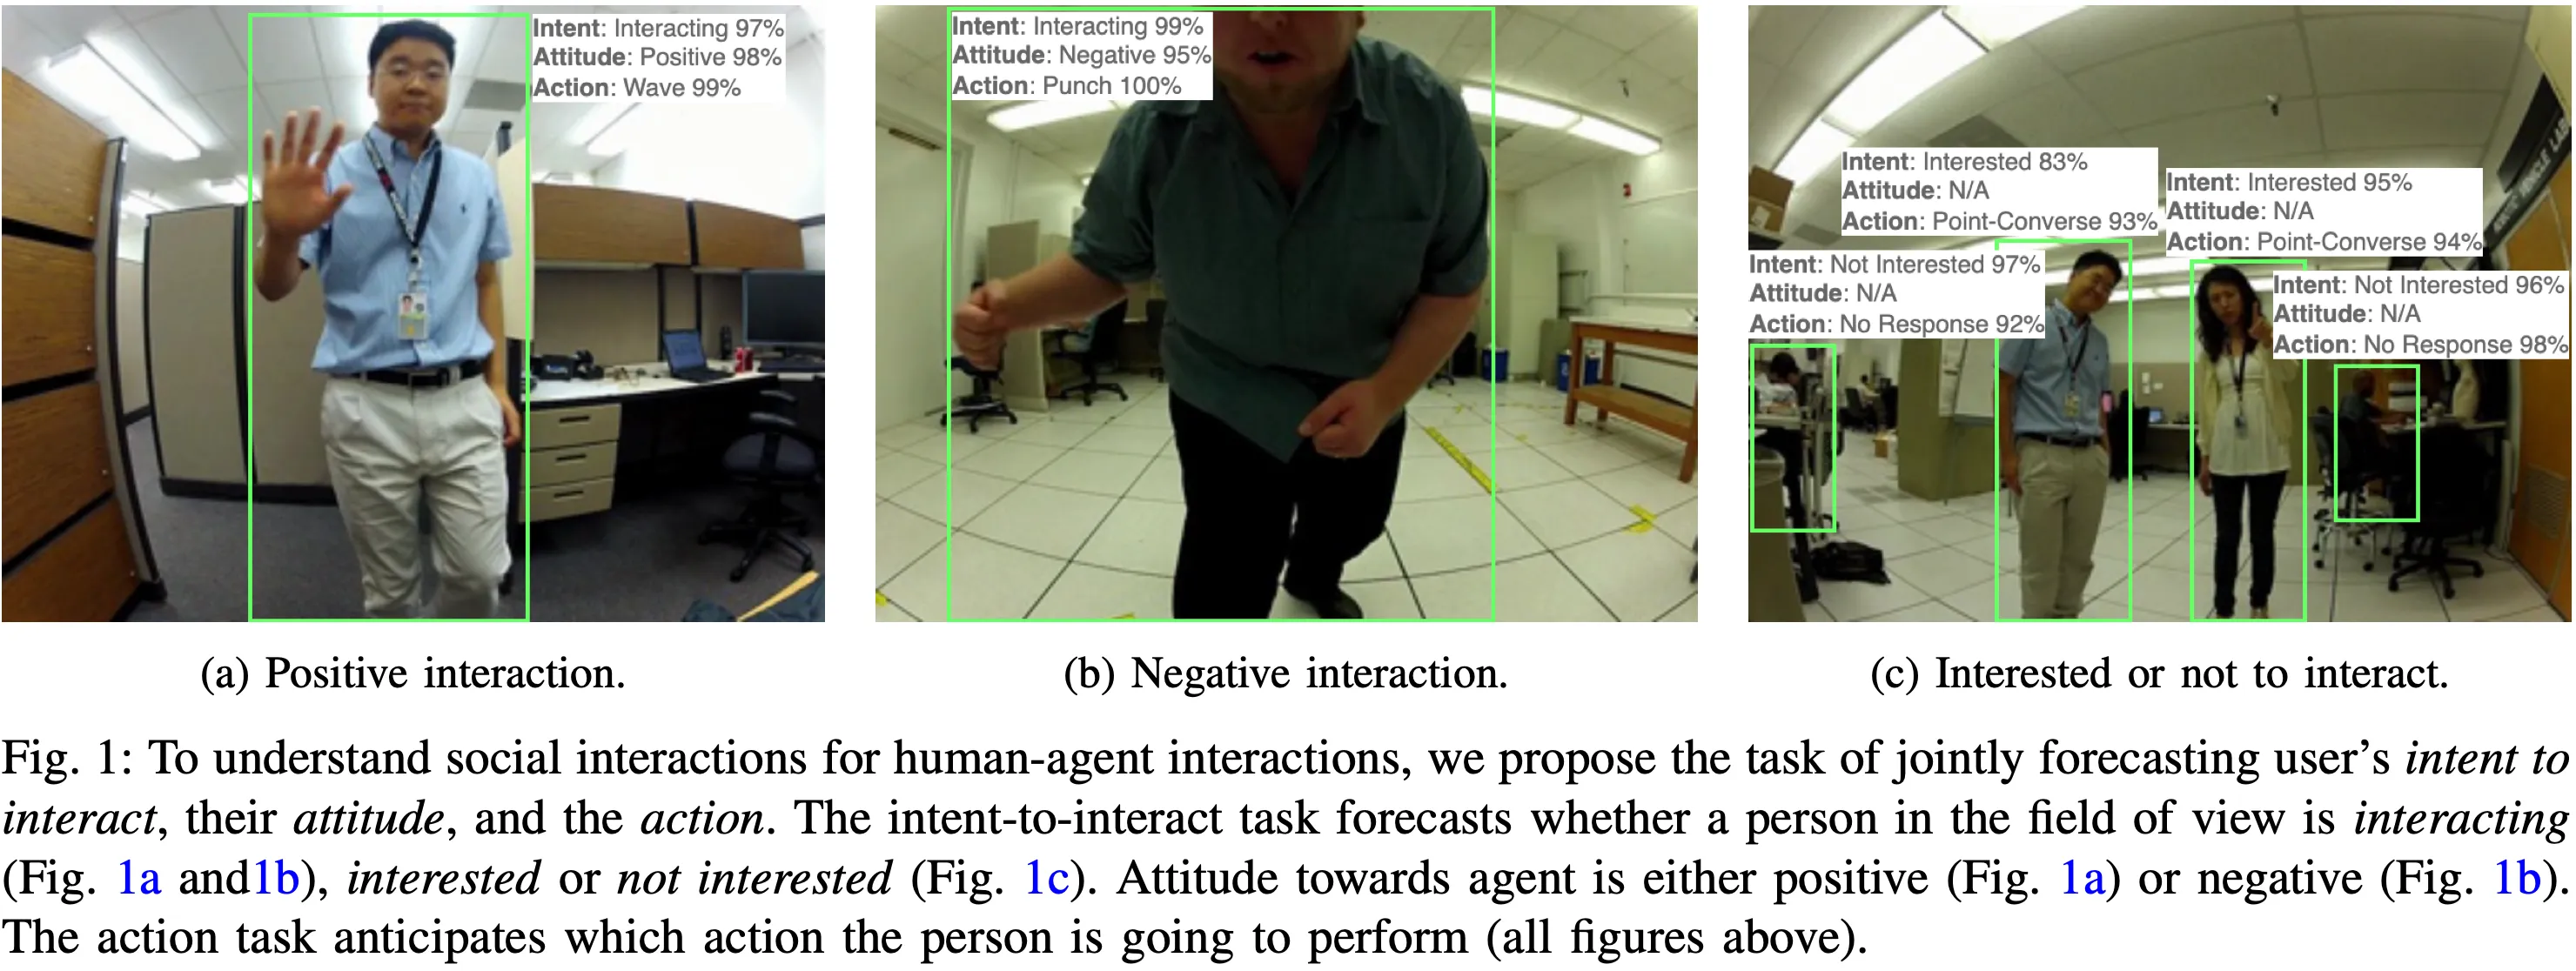
To interact efficiently, an agent should recognise its target user and prepare before the interaction starts; from one second of egocentric video, SocialEgoNet uses whole-body keypoints and hierarchical multitask learning to jointly forecast intent to interact, attitude and action in real time, reaching 83.15% average accuracy on the newly annotated JPL-Social dataset.
Abstract
For efficient human-agent interaction, an agent should proactively recognize their target user and prepare for upcoming interactions. We formulate this challenging problem as a novel task of jointly forecasting a person’s intent to interact with the agent, their attitude towards the agent and the action they will perform, from the agent’s (egocentric) perspective. We propose SocialEgoNet - a graph-based spatiotemporal framework that exploits task dependencies through a hierarchical multitask learning approach. SocialEgoNet uses whole-body skeletons (keypoints from face, hands and body) extracted from only 1 second of video input for high inference speed. For evaluation, we augment an existing egocentric human-agent interaction dataset with new class labels and bounding box annotations. Extensive experiments on this augmented dataset, named JPL-Social, demonstrate real-time inference and superior performance (average accuracy across all tasks: 83.15%) of our model outperforming several competitive baselines. The additional annotations and code are available at github.com/biantongfei/SocialEgoNet.
Cite
@INPROCEEDINGS{11210231,
  author={Bian, Tongfei and Ma, Yiming and Chollet, Mathieu and Sanchez, Victor and Guha, Tanaya},
  booktitle={2025 IEEE International Conference on Multimedia and Expo (ICME)},
  title={Interact with me: Joint Egocentric Forecasting of Intent to Interact, Attitude and Social Actions},
  year={2025},
  pages={1-6},
  doi={10.1109/ICME59968.2025.11210231}}